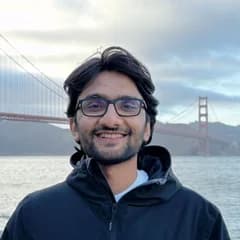
Ajay Yadav is the founder & CEO of neatlogs. He’s been running agents in production since 2024, and was one of the first people ever to take an agent to production (and keep it there).
Free · 1:1 · 25 mins
Bring us a real agent failure
In 25 minutes, we’ll help you figure out what to test, turn the failure into cases you can score, decide what AI can judge and what still needs a person, and work out how you’ll know if the agent is actually getting better.
- 01Your details
- 02Your agent
- 03Next step
Tell us about your agent
Takes about 2 minutes. We’ll save your answers before you choose a time. All fields are required unless marked optional.
Prompt changes are guesses without evals
You can fix one case and quietly break another.
A useful eval starts with the person who knows what good looks like. Sometimes that’s an engineer. Often it’s someone in support, operations, product, or another domain team. We’ll help turn that judgment into checks you can run every time the agent changes.
What you leave with
- The 3–5 failures worth evaluating first
- A clear definition of correct for each one
- What AI can score and what needs a person
- A small first eval suite your team can build
- Who should own each judgment
Meet the neatlogs team
Your working session will be with Ajay Yadav.
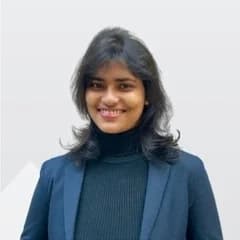
Antaripa Saha works with Hamel Husain & Shreya Shankar, and also leads evals at neatlogs. She spends most of her time on how teams design eval suites that survive contact with production.
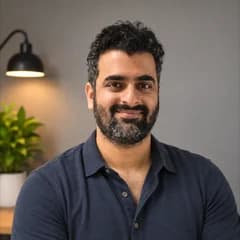
Akshay Hangloo leads engineering at neatlogs. He built the tracing and eval infrastructure the product actually runs on.
Who it’s for
If a call isn’t the best next step, we’ll email you what we think you should do instead.
Teams with an agent being used by customers or people inside the company, and a real problem they want to evaluate.
It’s not for personal projects or model benchmarking.